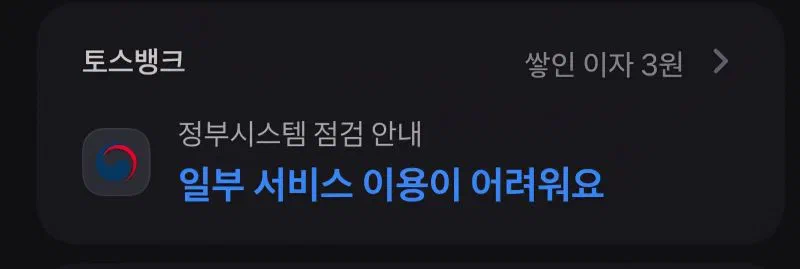
A fire recently broke out at a government data center, and recovery is still underway — you can still see the government-system notice up on Toss.
This isn’t the first time something like this has happened. There have been similar incidents before, and after one of them, the government announced plans to build an Active-Active level DR setup. In practice, though, implementation varies by ministry and by system, and most seem to still be at the Active-Passive or Warm-Standby stage.
I happen to have hands-on experience running a DR project at Coupang. What I took away from it is that it’s nowhere near as easy as it sounds.
First,
Onboarding an existing legacy system (whether on-prem or in the cloud) into a DR environment is far more complex than it looks.
Government systems likely differ ministry by ministry in development language, infrastructure, and operating practices, so migration ends up being a custom, one-by-one effort — making it nearly impossible to pull off in a short timeframe. It’s a project that’s more complex, and takes much longer, than it appears.
DR isn’t a project where you move everything over at once — it’s closer to fitting together a different puzzle piece by piece.
Second,
Optimizing RTO (Recovery Time Objective) and RPO (Recovery Point Objective) isn’t purely a technical problem.
Even a service that doesn’t demand the ultra-short RTO/RPO of a financial system or a commerce platform like Coupang — if it’s a nationwide government service — still needs recovery within tens of minutes to a few hours, and hitting that kind of short recovery window costs far more than you’d expect. And with many aging systems likely in the mix, the technical constraints were probably significant.
Third,
There were likely difficulties coordinating across ministries, too.
Governments don’t run every system themselves — much of it is outsourced or contracted out, vendor technical maturity varies widely, and there are simply too many stakeholders to align.
And given the conservative decision-making structures typical of public organizations, actually agreeing on and designing an Active-Active architecture would have been anything but easy.
In the end, DR is not a simple technical project.
It’s a comprehensive engineering challenge that only succeeds when technology, organization, budget, and decision-making structure all align at once.
Watching this incident unfold, I’m reminded again of just how hard — and how important — “perfect DR” really is. At Coupang, our own DR project ran into more difficulties than the ones above, but it’s now implemented at a high level, and we keep closing the remaining gaps through continuous review.
Disasters can strike at any time, but if recovery isn’t prepared in advance, the losses turn out far bigger than expected. I hope this incident, however overdue, becomes the push for government systems to finally get Active-Active DR right.
#DisasterRecovery #DR #ActiveActive #DigitalInfrastructure #CloudArchitecture #Resilience #TechLeadership #ITStrategy #Coupang #ProjectManagement